- Direct API call — the application sends a prompt to OpenAI or Anthropic and returns the response. No memory, no data grounding, no accuracy tracking.
- RAG-augmented integration — the system retrieves relevant context from a vector database before calling the model, reducing hallucination and giving the LLM access to proprietary data.
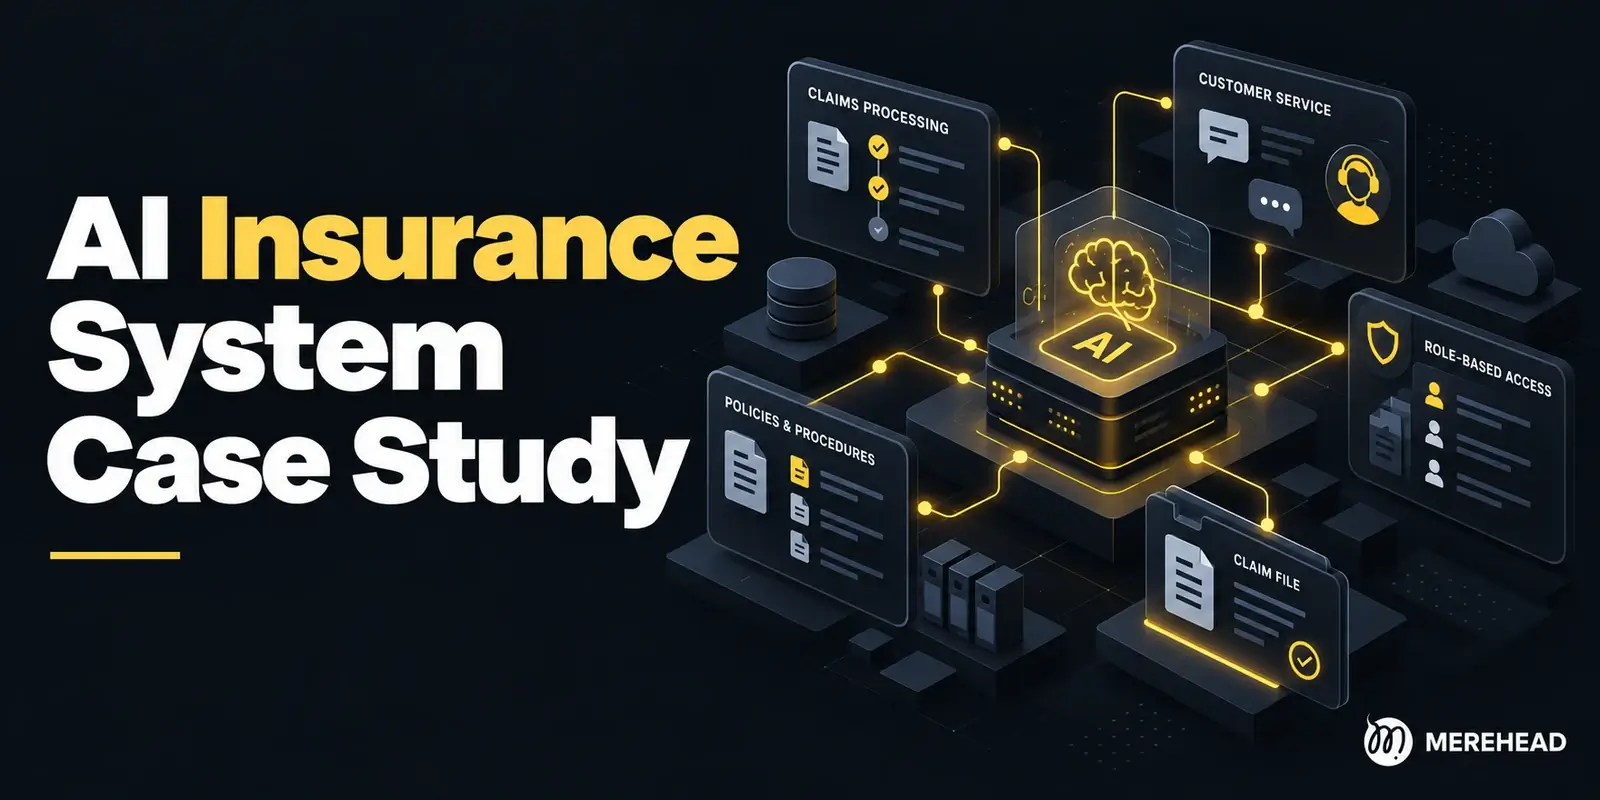
- Multi-agent orchestration — several specialized LLM agents run in parallel, each handling a narrow task, with a synthesis layer combining their outputs and a feedback loop that tracks accuracy over time.
Every enterprise integration conversation we've had over the past two years starts the same way: a CTO or product owner wants "ChatGPT integrated into the platform". Nobody wants a raw API call — they think they want that, until they see what a raw API call actually does under production traffic.
Why a Raw ChatGPT API Call Isn't an Integration Strategy
The Stateless Problem — No Memory Between Sessions
An LLM API call carries no memory of the previous call. Every request starts from zero unless you engineer state around it. That sounds obvious on a whiteboard, but it's the single biggest reason enterprise ChatGPT integration cost estimates blow past their original scope: teams budget for "the API call" and then discover they also need to budget for the memory layer, the retrieval layer, and the evaluation layer that make the API call useful in a real product.
We ran into this directly while architecting a hybrid AI chatbot development system for a trading signal platform. The client's original ask sounded simple: "let ChatGPT analyze market conditions and tell us what to do". We slowed the conversation down, because a stateless assistant genuinely can't do that job — it has no live data feed, no record of which past calls were right, and no mechanism to improve.
The moment a client says "AI that predicts outcomes", we stop and ask what they actually need — nine times out of ten it's a decision framework, not a prediction oracle.
 Yuri MusienkoBusiness developer, Merehead
No Accuracy Tracking, No Learning Loop
A ChatGPT assistant answering questions in isolation has no way to tell you whether its answer from last Tuesday was right. Without an evaluation loop sitting outside the model, "AI integration" becomes a black box that either works by accident or fails silently — and silent failure is worse than a crash, because nobody notices until the damage compounds.
The Architecture That Actually Scales
Data Layer — PostgreSQL and pgvector for Agent Memory
We standardize on a single PostgreSQL 16 instance with two extensions instead of bolting on a separate vector database: TimescaleDB for time-ordered data, pgvector for semantic search. This isn't a stack preference — it's a decision that removes an entire category of operational fragmentation.
Market and business data is fundamentally relational and time-ordered; time-bucketed aggregations, multi-table joins on timestamp, and window functions are SQL-native operations that a document store or a bolted-on vector service handles poorly by comparison.
pgvector solves the stateless problem directly. Before the system generates a new response, it queries the vector store for the most contextually similar past interactions and their outcomes — effectively giving a stateless LLM a form of long-term memory it doesn't have by default. This is the core of any serious AI integration into an app that needs to reason over accumulated history rather than a single prompt.
Multi-Agent Specialization vs. One Monolithic Prompt
A single LLM agent trying to handle technical analysis, sentiment interpretation, compliance checks, and customer intent in one prompt produces mediocre output across all four. We consistently get better results from specialization: multiple narrow agents, each with its own system prompt and a single domain of responsibility, feeding a synthesizer that weighs their outputs. Enterprise LLM integration architecture built this way scales by adding agents, not by rewriting a growing monolithic prompt every time a new use case appears.
The Learning and Evaluation Loop
The component that separates a system that "uses AI" from one that actually improves runs on three timescales: hourly pipeline execution and logging, daily evaluation of past outputs against real outcomes, and weekly recalibration of each agent's weight based on demonstrated accuracy. We built exactly this loop for a hybrid signal-generation system: six specialized agents (technical, sentiment, on-chain, news, macro, and a synthesizer) running on Claude Sonnet and Haiku, with OpenAI embeddings feeding pgvector.
| Component | Role | Why It Matters for ChatGPT Integrations |
| Data Layer (PostgreSQL + TimescaleDB + pgvector) | Stores structured data and vector embeddings in one instance | Removes the need for a separate vector database and keeps retrieval fast at scale |
| Specialized LLM Agents | Each agent handles one narrow domain | Prevents the "does everything, does nothing well" failure of a single monolithic prompt |
| Synthesizer Agent | Combines agent outputs with dynamic accuracy weighting | Downweights underperforming logic automatically instead of trusting every response equally |
| Evaluation Loop | Checks past outputs against real outcomes on a schedule | Turns "AI integration" into a system that gets measurably better over time |
What Breaks in Production (And How We Fixed It)
The API-Key Dependency Bottleneck
Challenge: On a multi-integration platform, development stalled because several required third-party API keys — for payment, compliance, and exchange integrations — sat unresolved in a general backlog instead of being flagged as a blocker. Nobody owned the gap until it had already cost the team days.
Solution: We pulled every external API and key dependency into a single explicit tracked list and assigned it directly to the client as a blocking dependency, separate from our engineering backlog. Meanwhile, the team kept working through everything that didn't depend on the missing keys, prioritizing fixes from one authoritative bug-tracking document instead of scattering effort.
Result: The team closed roughly 80% of outstanding issues within days while the client sourced the missing credentials, and development never fully stalled despite the blocking dependency. The same pattern applies directly to ChatGPT and OpenAI integrations: quota approval, billing setup, or key provisioning on the client side is a common hidden bottleneck if nobody names it explicitly on day one.
Observability Gaps in Real-Time API Delivery
Challenge: On a live trading platform, real-time charts and order book data stopped reaching the client's front end even though the WebSocket connection itself established successfully. The team had no centralized logging, so nobody could tell whether the break was happening at the socket layer, the backend, or the front end.
Solution: We implemented centralized log aggregation across all three layers of the delivery path, giving the team a way to trace the failure point instead of guessing. We paired this with database isolation to rule out load as a contributing cause.
Result: The team localized and resolved the break within a single sprint, and the platform kept a permanent observability layer afterward. That same discipline applies to any LLM API integration — without per-call logging, a timeout or a silent failure on the provider's side is indistinguishable from "the model just didn't respond", and debugging turns into guesswork.
Frontend Request Overload Hitting Rate Limits
Challenge: A trading platform crashed at roughly 72% of target load during stress testing — before a single order was even placed. The root cause wasn't backend logic; it was the front end firing unnecessary requests for data the user hadn't asked to see yet.
Solution: The team isolated the database onto its own instance to reduce load on the core server and cut the redundant frontend calls that triggered the cascade in the first place.
Result: The platform passed subsequent load tests without the early failure point. For OpenAI or Anthropic API rate limits specifically, the same lesson holds — client-side code that fires "just in case" LLM calls is usually what exhausts a rate-limit budget first, not the actual user-facing logic.
Production-readiness checklist for any enterprise ChatGPT integration:
- Per-call logging across every layer of the request path (client, API gateway, model provider)
- Explicit tracking of API key and quota dependencies as blocking items, owned by name
- Rate-limit handling with backoff and request deduplication on the client side
- A vector-memory layer if the use case needs any continuity across sessions
- A scheduled evaluation loop that checks model outputs against real outcomes
- A fallback provider or degraded mode for when the primary LLM API is unavailable
Direct API Call vs. Custom Multi-Agent Integration
| Factor | Direct ChatGPT API Call | Custom Multi-Agent Integration |
| Memory persistence | None — stateless per call | Vector-backed memory across sessions |
| Cost predictability | Scales linearly with token volume, hard to forecast | Bounded by architecture; caching and deduplication cut redundant calls |
| Accuracy tracking | Not built in | Evaluation loop scores every output against outcomes |
| Failure visibility | Silent — bad output looks identical to good output | Logged and traceable per agent, per call |
| Scalability to new use cases | Requires rewriting the prompt | Add a new specialized agent without touching the core |
A single LLM call is a demo. A multi-agent system with memory and an evaluation loop is a product you can actually put in front of stakeholders and defend the numbers on.
Yuri MusienkoBusiness developer, MereheadHow Much Does a ChatGPT Integration Actually Cost?
Simple API Integration: $400–$2,500
A single external API integration at this complexity level — comparable to a bank API or KYC service connection we've priced on fintech platforms — runs $400 to $2,500 depending on how much backend logic wraps the call. This tier covers a straightforward request-response bridge: no memory, no retrieval, no evaluation. It's appropriate for a support chatbot answering FAQs, not for anything making business-critical decisions.
Production-Grade System with Memory and Monitoring: $20,000–$60,000+
Once the requirement includes persistent memory, multi-agent reasoning, an evaluation loop, and observability, the project moves into a different bracket entirely — the same bracket as a security hardening pass or a custom payment gateway widget on a trading platform, both of which we've priced at $20,000 and up. A proof-of-concept for a hybrid LLM system with six specialized agents, vector memory, and a learning loop typically runs 4–6 weeks of development, with the final number depending on data source coverage, dashboard depth, and integration count.
Recurring Infrastructure Costs
Post-launch, the ongoing bill for a production LLM integration of this scope lands around $270–$400 a month: LLM API usage (roughly $50–$100 for a Claude Sonnet/Haiku split), embeddings ($20–$50), VPS and database hosting ($50–$100), and any paid third-party data subscriptions the system depends on (~$150). Budget separately for maintenance — in our experience, 25–30% of ongoing effort on systems like this goes to data resilience (provider outages, API changes, methodology shifts), not core model logic.
| Tier | Scope | Typical Cost |
| Simple integration | Single API call, no memory, minimal logic | $400 – $2,500 |
| Mid-complexity module | Admin-configurable prompts, basic logging, single-agent | $8,000 – $16,000 |
| Production multi-agent system | Vector memory, multiple agents, evaluation loop, dashboard | $20,000 – $60,000+ |
| Recurring monthly cost | API usage, embeddings, hosting, data subscriptions | $270 – $400/month |
Realistic Timelines and Team Composition
A working proof-of-concept for a production-grade LLM integration — data layer, ML models where relevant, specialized agents, vector memory, evaluation loop, and a dashboard — takes 4–6 weeks when the architecture is defined upfront rather than discovered mid-build.
| Week | Milestone | Deliverables |
| 1 | Data layer | PostgreSQL with TimescaleDB and pgvector deployed; API integrations live; historical backfill complete |
| 2 | Models and vector memory | Core models trained with walk-forward validation; historical context embedded into the vector store |
| 3 | Agent layer | Specialized agents implemented and tested against historical scenarios; synthesizer integrated |
| 4 | Learning loop and dashboard | Hourly pipeline live; evaluator and retraining jobs scheduled; dashboard and notification channel operational |
| 5–6 | Hardening and handover | Live-observation refinements, documentation, production deployment, knowledge transfer |
Team composition for this scope typically includes a business analyst and project manager for scoping, a backend engineer (Python/FastAPI is our default for the AI layer, Node.js where the core product logic lives separately), an AI/ML engineer for the agent and evaluation layer, a DevOps engineer for deployment and monitoring, and QA. For teams weighing a narrower AI agent build against this full scope, our breakdown of AI agent development cost separates out pricing by component so you can scope just the pieces you need.
If the integration sits inside a trading or fintech product specifically, the underlying data infrastructure has to handle the same load patterns as the exchange itself — our guide to crypto exchange architecture covers the partitioning and latency principles that carry over directly into an LLM-driven signal pipeline built on top of that data.
FAQ
A simple API-level integration with no memory or evaluation runs $400–$2,500. A production-grade system with vector memory, multiple specialized agents, and an evaluation loop runs $20,000–$60,000+, plus roughly $270–$400/month in recurring API and infrastructure costs.
Every API call to a large language model is stateless — the model has no built-in memory of prior calls. Persistent memory requires an external layer, typically a vector database like pgvector, that retrieves relevant past context before each new call.
A working proof-of-concept with a data layer, specialized agents, vector memory, and an evaluation loop typically takes 4–6 weeks when the architecture is scoped before development starts.
For low-stakes FAQ-style interactions, yes. For anything involving business decisions, compliance, or continuity across sessions, a single stateless call will not track accuracy or retain context, and it tends to fail silently under load.
In our experience, the two most common causes are unmanaged API rate limits triggered by redundant client-side calls, and missing observability that makes it impossible to tell whether a failure originated at the client, the API gateway, or the model provider.