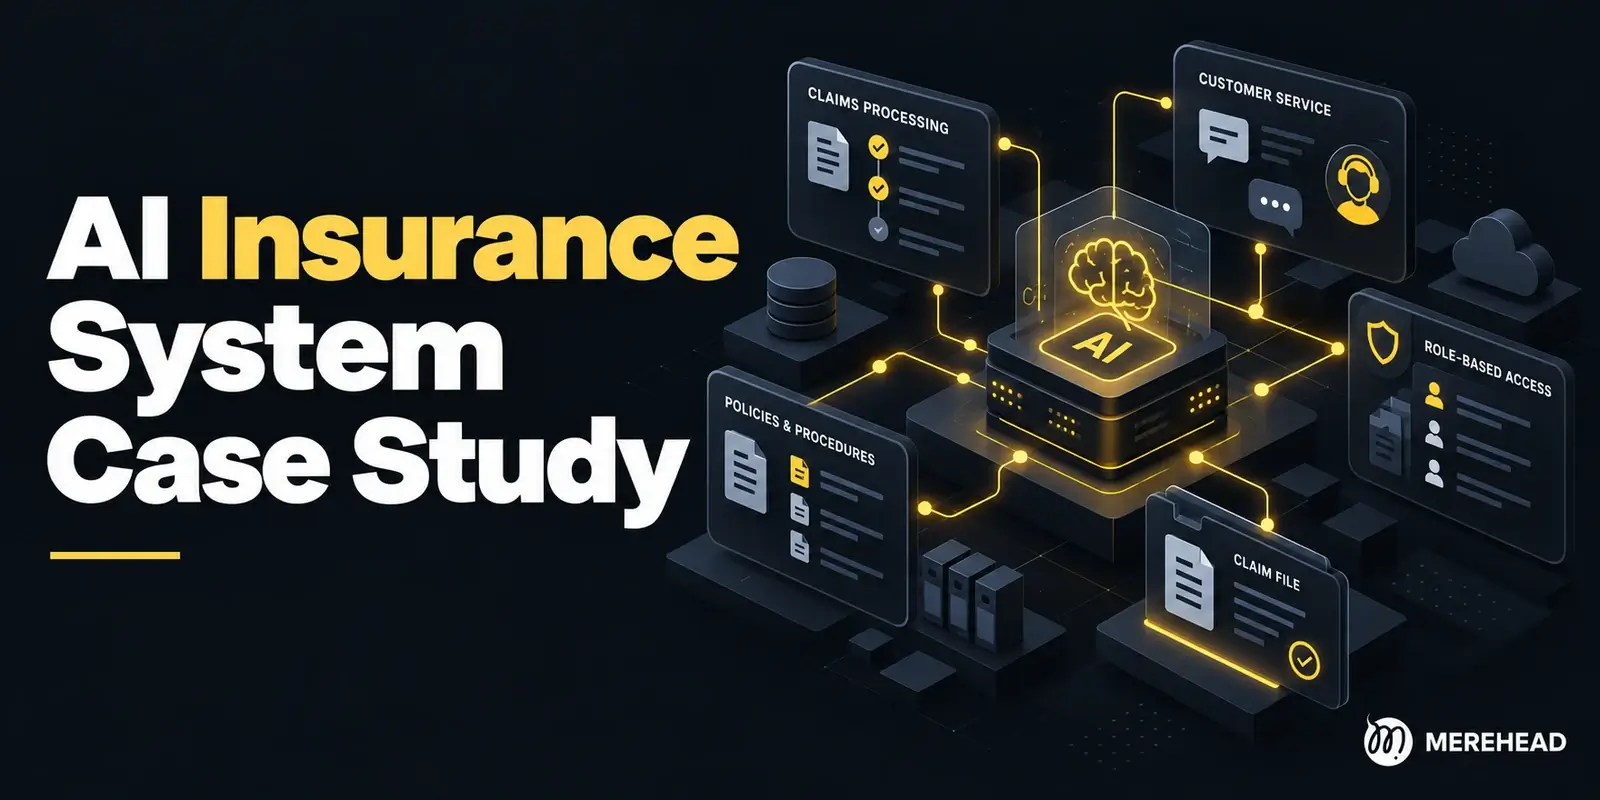
AI chatbot development cost ranges from $5,000 for a rule-based FAQ bot to $80,000+ for a multi-agent enterprise system with orchestration, vector memory, and dedicated infrastructure.
The final number depends on four layers, not one:
- Conversation logic layer — scripted flows vs. LLM-driven reasoning vs. multi-agent orchestration
- Memory layer — none, session-only, or persistent vector memory (RAG) across conversations
- Infrastructure layer — shared hosting vs. Kubernetes with dedicated worker nodes and secret management
- Recurring costs — LLM API usage, embeddings, monitoring, and data resilience, typically $270–$400/month for a mid-complexity system
Every CTO who asks "how much does an AI chatbot cost" is really asking a different question: what am I buying at each price point, and where does the money actually go. A $5,000 bot and a $60,000 bot don't just differ in polish — they're architecturally different systems solving different problems.
This breakdown walks through the real cost drivers, using pricing structures and engineering decisions we've pulled from our own project estimates and delivery data.
A single LLM call answering support tickets is a demo. A system that routes, remembers, and gets measurably better over time is a product — and that's where the cost conversation actually starts.
 Yuri MusienkoBusiness developer, Merehead
The Three Cost Tiers of AI Chatbot Development
We break chatbot projects into three tiers based on what the conversation engine actually does under the hood — not on vague "basic/pro/enterprise" labels that vendors use to obscure what you're paying for.
Tier 1 — Rule-Based / FAQ Bots ($5,000–$15,000)
No LLM in the loop, or a thin LLM wrapper over a decision tree. The bot matches intents against a fixed knowledge base and returns pre-written answers. Development time runs 2–4 weeks. This tier makes sense when your support volume is predictable and your questions don't vary much — password resets, order status, shipping policy. It breaks the moment a user asks something outside the script, because there's no reasoning layer to fall back on.
Tier 2 — RAG-Powered Bots with Memory ($15,000–$35,000)
One LLM provider, a vector database for retrieval-augmented generation, and persistent memory across a conversation. This is where most serious business chatbots land. In one of our commercial estimates, adding a multilingual AI consultant module — with reasoning over platform-specific content rather than scripted responses — moved a project from a $27,000 baseline to $35,000, an $8,000 delta for the AI layer plus the compliance logic it required to sit alongside. That number lines up with what we typically quote for this tier when a client wants natural-language understanding without full multi-agent orchestration.
Tier 3 — Multi-Agent Enterprise Systems ($40,000–$80,000+)
Multiple specialized agents, dynamic routing based on query complexity, dedicated Kubernetes infrastructure, and a learning loop that improves the system over time. Timeline runs 6–10 weeks for a working system, longer for full production hardening. This is the tier where the architecture decisions in the rest of this article actually matter, because a single misconfigured resource limit or an unoptimized routing layer can double your monthly LLM bill without anyone noticing until the invoice arrives.
| Tier | What's included | Budget range | Typical timeline |
| Rule-based / FAQ bot | Scripted flows, no LLM reasoning | $5,000–$15,000 | 2–4 weeks |
| RAG bot with memory | Single LLM provider, vector memory, one integration | $15,000–$35,000 | 4–6 weeks |
| Multi-agent enterprise system | Router + specialized agents, K8s, secret management, monitoring | $40,000–$80,000+ | 6–10 weeks |
What Actually Drives the Price: A Component-Level Breakdown
Vendors quote a single number because it's easier to sell. We break estimates down by module, because that's the only way a CTO can tell what he's actually paying for and where he can cut scope without breaking the product. Here's a real module-level breakdown from one of our platform builds, adapted to show how the same logic applies to chatbot architecture:
| Module | Real project cost (reference) | Chatbot equivalent |
| Microservices architecture setup | $12,000 | Agent orchestration layer |
| External API/node integrations (per integration set) | $15,000 | LLM provider + third-party data source integrations |
| Personal account / dashboard module | $9,000–$13,000 | Admin panel + conversation analytics dashboard |
| Aggregated balance/data view | $18,000–$27,000 | Cross-conversation memory + reporting layer |
Orchestration Layer (Router + Specialized Agents)
The single most expensive architectural mistake we see is routing every incoming message through one heavyweight model. A client came to us with exactly this setup: every query — simple or complex — hit the same LLM, and token cost scaled linearly with traffic while response quality stayed flat.
Challenge: The team ran every user message through a single, expensive model call regardless of complexity. Simple FAQ-style queries and genuinely complex multi-step requests consumed identical compute, and there was no mechanism to control cost as traffic grew.
Solution: We introduced a router agent that classifies incoming queries by complexity before any expensive model call happens. Simple, repetitive queries get served by a lightweight model or a cached Redis response; complex queries route to a higher-capability model with access to agent memory through pgvector. We orchestrated this through n8n, and each agent runs on its own worker pool in Kubernetes with independent resource limits, so a traffic spike on one channel doesn't trigger the OOM-killer for unrelated services.
Result: Token cost per query dropped by a significant margin for typical traffic, since the bulk of real-world queries are simple, while latency on genuinely complex requests stayed unaffected because they run on a separately provisioned worker pool. This same principle — matching query complexity to model cost — is exactly what we cover in our breakdown of AI agent development cost, since agent orchestration overhead scales with the number of specialized components you run.
Vector Memory & RAG Infrastructure (pgvector vs. Dedicated Vector DB)
Every LLM call is stateless by default — the model has no memory of the last message unless you build a memory layer explicitly. This is the single biggest gap between a "chatbot demo" and a production system.
Market data and conversation data share a property most teams miss: both are fundamentally relational and time-ordered. Adding a dedicated vector database like Pinecone alongside your primary database introduces operational complexity — a second system to monitor, back up, and secure — without a real performance gain at the data volumes most chatbot projects operate at.
Yuri MusienkoBusiness developer, MereheadChallenge: Without persistent memory, a chatbot re-answers the same question from scratch every time a similar situation appears, producing inconsistent responses and repeating errors it already "resolved" in a previous conversation.
Solution: We added an agent memory layer using pgvector on top of the existing PostgreSQL instance — no separate vector database. Every conversation and its outcome gets embedded and stored. Before generating a new response, the system queries the vector store for similar past interactions and their resolutions, then grounds the new answer in that retrieved context.
Result: Responses stay grounded in actual precedent instead of pure model inference, which is the same mechanism that gave one of our AI signal systems 54–58% directional accuracy under honest validation — a number lower than the inflated 70%+ figures most vendors quote, but one that holds up in production. For teams weighing this decision, our guide on integrating AI into an app covers the memory architecture trade-offs in more depth.
Async Processing & Queue Infrastructure (Redis/Kafka)
Challenge: A client's synchronous chatbot setup fell over during traffic spikes — the application server, database, and message queue all ran on the same instance, so a marketing email blast that drove a sudden influx of conversations caused resource deadlock. Requests started timing out, and some messages disappeared entirely when a service restarted mid-conversation.
Solution: We moved message processing to an async worker layer built on Redis and Kafka. The HTTP service accepts an incoming message and immediately queues it; workers process LLM API calls independently, with retry and backoff logic for provider timeouts. We wrote custom session lifecycle handling to close connections cleanly on restart, since the framework didn't support Kafka natively out of the box. API keys for LLM providers moved into HashiCorp Vault with JWT-based authentication instead of sitting in environment variables.
Result: The system now absorbs traffic spikes without downtime on the request-intake layer, DevOps response time on runtime incidents runs 30–60 minutes, and message loss during restarts is gone thanks to proper session lifecycle management. This same asynchronous pattern underlies the notification architecture in our AI trading bot development guide, where reliable message delivery under load matters just as much as it does for chatbot traffic.
Recurring Costs Nobody Talks About
The development invoice is one-time. The bill that keeps arriving every month is the one most estimates leave out. Here's a real recurring cost breakdown from one of our production AI systems, post-launch:
| Item | Estimated monthly cost (USD) |
| LLM API usage (mixed model tiers) | $50–$100 |
| Embedding API or self-hosted embeddings | $20–$50 |
| VPS + database infrastructure | $50–$100 |
| Third-party data API subscriptions | ~$150 |
| Total recurring | ~$270–$400/month |
LLM API Costs at Scale
Token cost isn't fixed — it's a function of how well you route queries to the right model tier. Sending every message to your most capable (and most expensive) model is the fastest way to burn budget on traffic that didn't need it. The router-agent pattern described earlier — cheap model for simple queries, capable model for complex ones — is the single highest-leverage cost control most teams skip.
Infrastructure & DevOps
Kubernetes with proper CPU/RAM requests and limits prevents throttling and unexpected OOM-kills under load. GitLab CI/CD with a single Helm chart across services keeps deployment consistent, and HashiCorp Vault with JWT authentication is the baseline for handling API keys in any system touching customer data — not an optional add-on. Grafana plus a log aggregation layer gives you the observability to catch a runaway cost spike before it shows up on the invoice instead of after.
Custom Development vs. Off-the-Shelf Platforms
| Factor | Off-the-shelf platform | Custom development |
| Upfront cost | Lower ($0–$5,000 setup) | Higher ($15,000+) |
| Recurring cost | Per-seat or per-conversation licensing, scales unpredictably | Infrastructure + API cost, scales linearly and predictably |
| Control over routing/model choice | Limited to platform's supported models | Full control, can mix providers per query type |
| Vendor lock-in | High — data and logic live in the platform | Low — you own the orchestration layer |
| Scalability ceiling | Bound by platform's architecture | Bound by your own infrastructure decisions |
No-code bot builders solve the first month. They rarely survive the first enterprise contract that asks about data residency, custom routing logic, or audit trails.
Yuri MusienkoBusiness developer, MereheadFor teams still weighing this decision, our overview of LLM development covers how model selection and orchestration patterns differ once you move past a platform's default configuration.
Security & Compliance Costs for Enterprise Chatbots
A chatbot handling customer data — support tickets, account details, transaction history — carries the same compliance weight as any other customer-facing service. Secret management through Vault with JWT authentication isn't a nice-to-have at this scale; it's the baseline we've built into every production system touching sensitive data, precisely because API keys sitting in plaintext environment variables are the most common way credentials leak in incident post-mortems.
Budget for this layer separately from the "AI logic" line item. It typically adds 10–15% to a Tier 2 or Tier 3 project, and it's the part of the estimate clients most often try to cut — right up until a security review flags it during procurement.
Real Timeline: From POC to Production
A 4–6 week POC timeline is achievable when the architecture is defined upfront and the stack is one the team works with daily — not when it's assembled ad hoc per project. Here's what that timeline looks like in practice, based on a comparable AI system build:
| Week | Milestone |
| 1 | Data layer and integrations live, historical backfill complete |
| 2 | Core memory and retrieval layer trained and validated |
| 3 | Agent logic implemented and tested against real scenarios |
| 4 | Learning loop live, dashboard and delivery channels operational |
| 5–6 | Hardening, production deployment, knowledge transfer |
A POC isn't a technical milestone — it's a business decision tool. If the signal doesn't hold up under honest validation at the POC stage, scaling it further doesn't fix that; it just makes the failure more expensive.
Yuri MusienkoBusiness developer, MereheadTeams scoping their first AI build often ask how this compares to a broader AI application, not just a chatbot — our guide on how to create an AI app breaks down team composition and realistic pricing across complexity tiers for that wider scope.
Post-Launch: Support & Maintenance Pricing
Launch isn't the finish line — a chatbot handling live traffic needs ongoing fixes, model updates, and monitoring response. Real support tiers from our own maintenance contracts, adapted to chatbot-scale projects:
| Tier | Response SLA | Included dev hours/month | Price |
| Basic | 1 business day | 20 hours | $3,000/month |
| Advanced | 4 hours (business days) | 30 hours | $4,200/month |
| Premium | 1 hour (business days) | 70 hours | $6,500/month |
| 24/7/365 | Round-the-clock | 150 hours | $12,000/month |
How to Get an Accurate Estimate for Your Specific Chatbot
Every number in this article is a reference point, not a quote. Your actual cost depends on how many data sources the bot needs to reason over, how many specialized agents your use case actually requires, and what compliance requirements apply to the data it touches. Send us your requirements and our Solutions Architect will send back a per-module hour breakdown within 48 hours, at no cost.
FAQ
Costs range from $5,000 for a rule-based FAQ bot to $80,000+ for a multi-agent enterprise system with dedicated infrastructure. Most business-grade chatbots with memory and reasoning land between $15,000 and $35,000.
A rule-based bot uses scripted decision trees and costs $5,000–$15,000. A RAG-powered bot adds an LLM provider and a vector memory layer for context-aware responses, typically costing $15,000–$35,000 and taking 4–6 weeks to build.
Enterprise systems require multiple specialized agents with dynamic routing, dedicated Kubernetes infrastructure with proper resource isolation, secret management through tools like Vault, and a learning loop that improves accuracy over time — each of these is a separate engineering workstream.
For a mid-complexity system, expect $270–$400/month: LLM API usage, embedding API costs, VPS and database infrastructure, and any paid third-party data subscriptions the bot relies on.
A working POC for a RAG-based system typically takes 4–6 weeks. Multi-agent enterprise systems take 6–10 weeks to reach a working state, with additional time for production hardening.
Routing queries by complexity — cheap model for simple requests, capable model for complex ones — cuts token cost significantly for typical traffic without sacrificing response quality on harder queries. Single-provider setups are simpler but scale cost linearly with volume regardless of query complexity.